AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup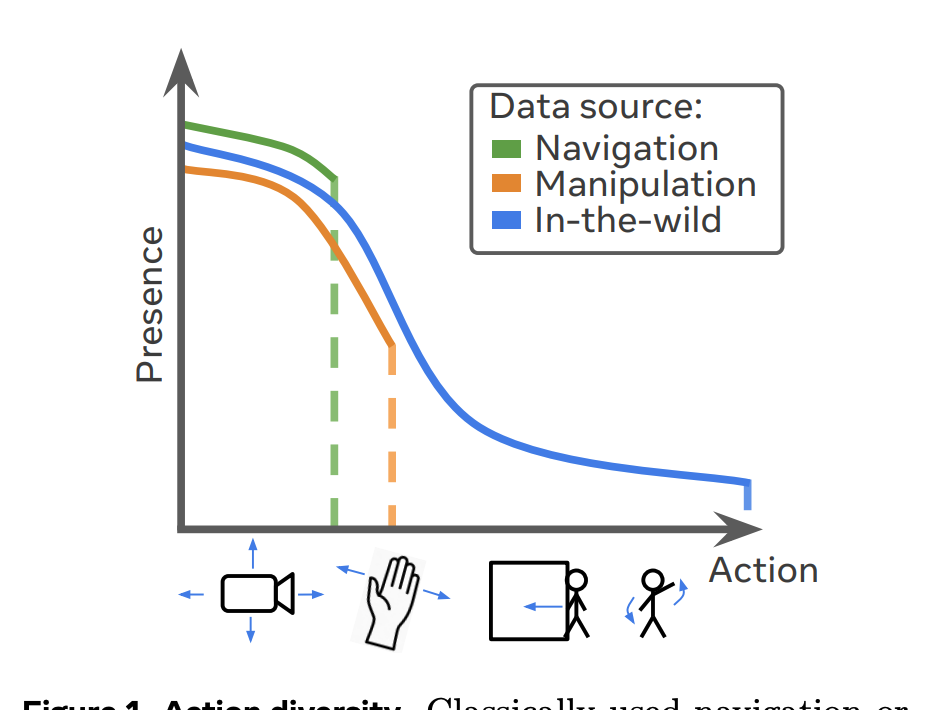
Learning Latent Action World Models In The Wild
Meta AI researchers address learning world models from in-the-wild videos without requiring explicit action labels, expanding beyond simple robotics simulations and video games to real-world video data with diverse embodiments and uncontrolled conditions.
Extending Context by Dropping Positional Embeddings
DroPE introduces a method for extending a language model’s context window after pretraining without expensive long-context fine-tuning. The approach involves removing positional embeddings from a pretrained model and performing brief recalibration at the original context length.
Self-Evolving Search Agents Without Training Data
Dr. Zero introduces a framework for developing multi-turn search agents that improve themselves autonomously without labeled training data. A proposer generates diverse questions to train a solver initialized from the same base model, creating a self-evolution loop with automated curriculum difficulty scaling.
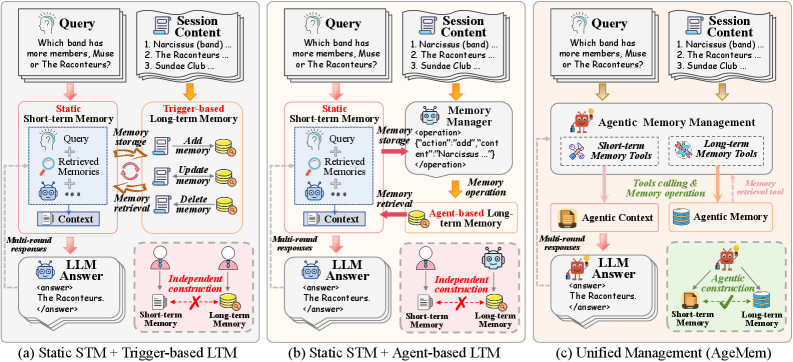
Unified Long-Term and Short-Term Memory for LLM Agents
AgeMem introduces a unified framework that integrates both long-term and short-term memory operations into an LLM agent’s decision-making policy. The system enables agents to autonomously determine what and when to store, retrieve, update, summarize, or discard information by exposing memory operations as tool-based actions.
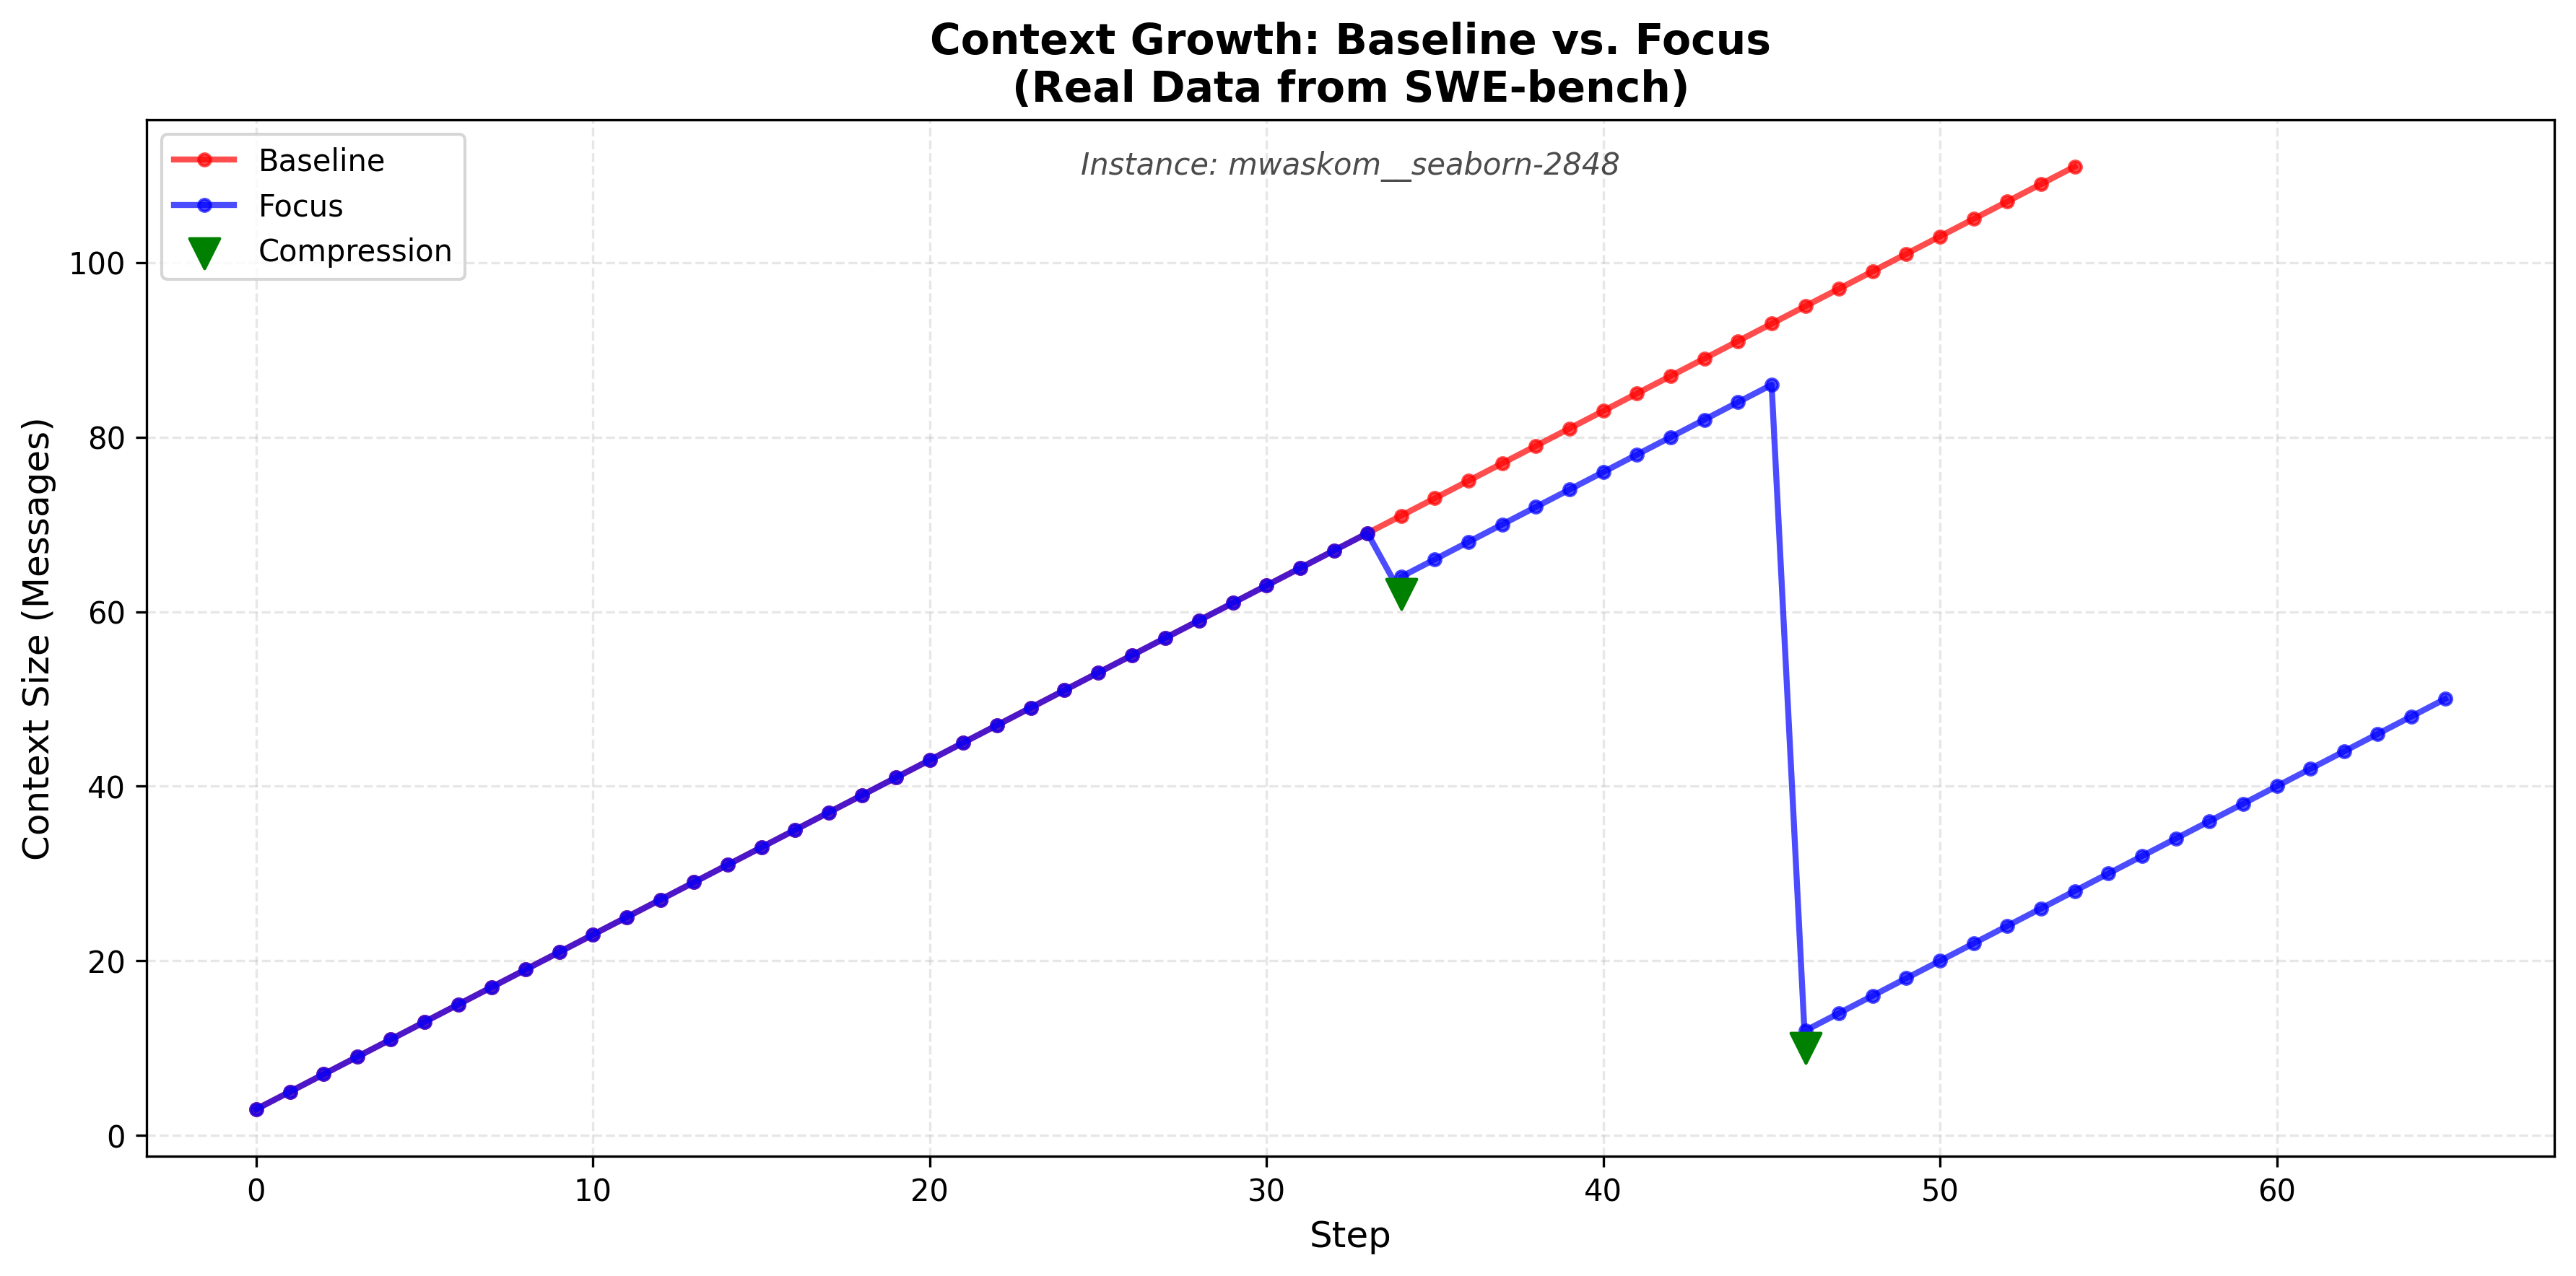
Active Context Compression for LLM Agents
Focus introduces an agent-centered architecture that enables LLM agents to autonomously manage their own memory by deciding when to consolidate learnings into a persistent “Knowledge” block and actively prune raw interaction history. The design is inspired by the biological navigation patterns of Physarum polycephalum (slime mold).
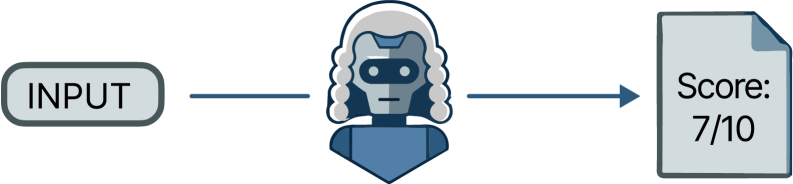
Agent-as-a-Judge
This comprehensive survey traces the evolution from LLM-based evaluation to agentic evaluation approaches, establishing the first taxonomy for this paradigm shift. As evaluation tasks grow more intricate and specialized, traditional single-pass language model judges become insufficient.
Efficient Lifelong Memory for LLM Agents
SimpleMem introduces a memory framework built on semantic lossless compression that addresses the tension between maintaining comprehensive long-term memory and minimizing token overhead for LLM agents. The approach achieves a 26.4% F1 improvement over baselines while reducing token consumption by up to 30-fold during inference.
Ministral 3
Mistral AI releases Ministral 3, a family of compact language models (3B, 8B, 14B parameters) designed for compute and memory-constrained applications from mobile to edge deployments. Created through Cascade Distillation (iterative pruning with continued training), each size offers pretrained, instruction-finetuned, and reasoning variants with integrated image understanding, released under Apache 2.0.
UniversalRAG
UniversalRAG introduces a RAG system that handles knowledge retrieval from heterogeneous sources containing multiple data types (text, images, videos) with varying granularities. Rather than forcing diverse modalities into a single embedding space where embeddings cluster by modality rather than meaning, it uses modality-aware routing to dynamically select appropriate corpus and granularity for each query, outperforming both unimodal and unified multimodal RAG baselines across 10 benchmarks.
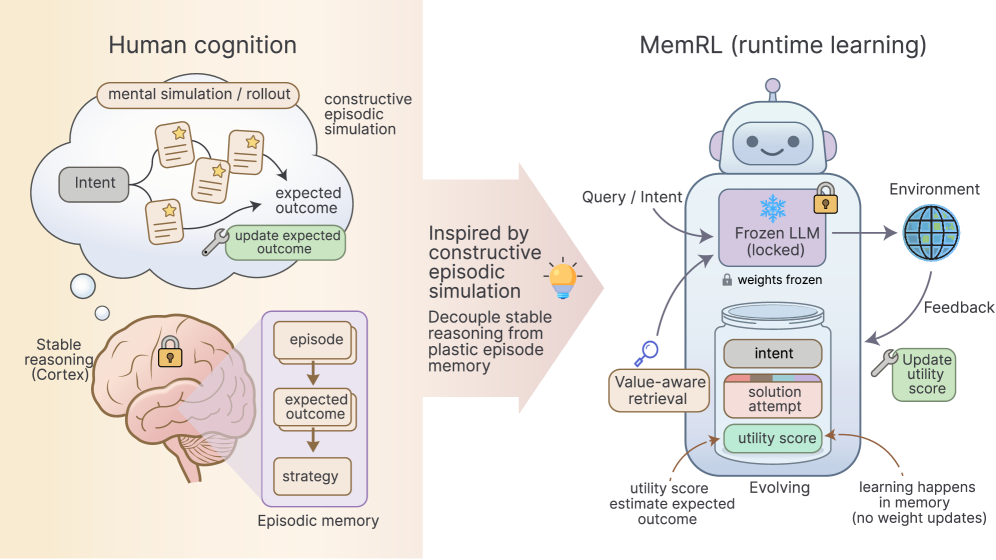
MemRL
MemRL enables LLM agents to improve continuously without retraining by separating a frozen model’s reasoning from an evolving memory system. A Two-Phase Retrieval mechanism filters candidates by semantic relevance, then ranks them using learned Q-values that improve through trial-and-error, outperforming existing methods on HLE, BigCodeBench, ALFWorld, and Lifelong Agent Bench.
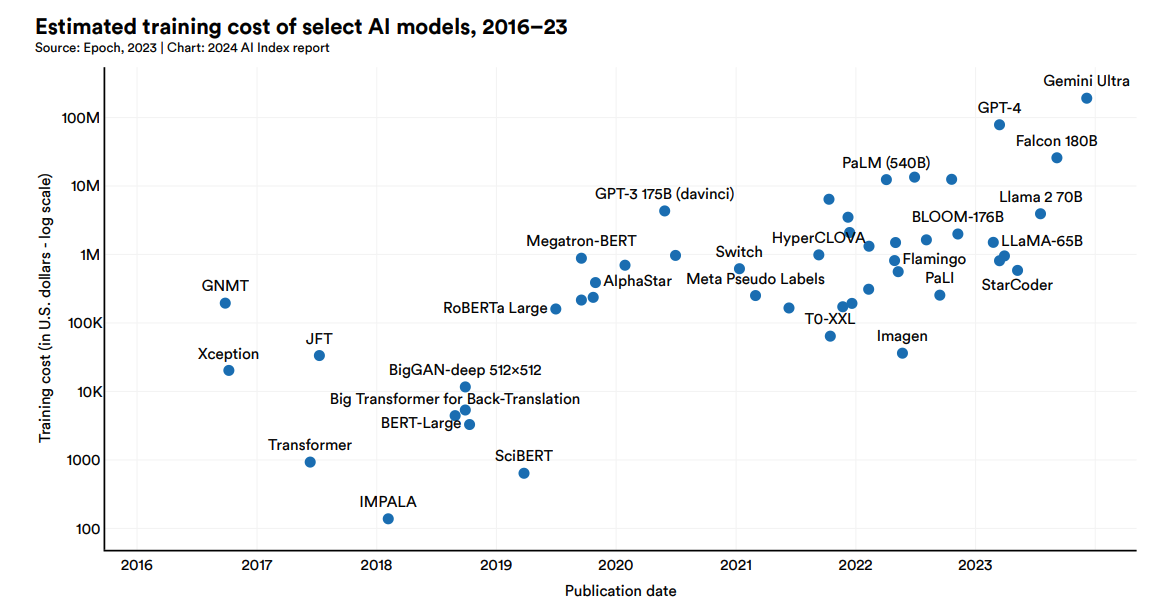
On the Slow Death of Scaling
This essay by Sara Hooker challenges the decade-long assumption that scaling compute always leads to better AI performance. It argues that the relationship between training compute and performance is highly uncertain and rapidly changing, with smaller models now routinely outperforming much larger ones.
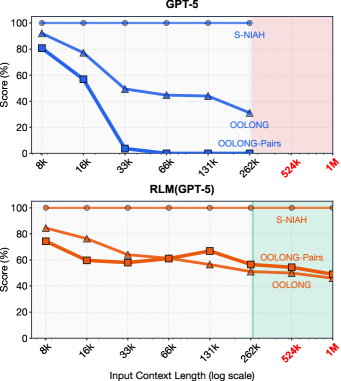
Recursive Language Models
Recursive Language Models (RLMs) are a general inference strategy that allows LLMs to process arbitrarily long prompts by treating them as part of an external environment. Rather than feeding long contexts directly into the model, RLMs load the prompt as a variable in a Python REPL and let the LLM programmatically examine, decompose, and recursively call itself over snippets.
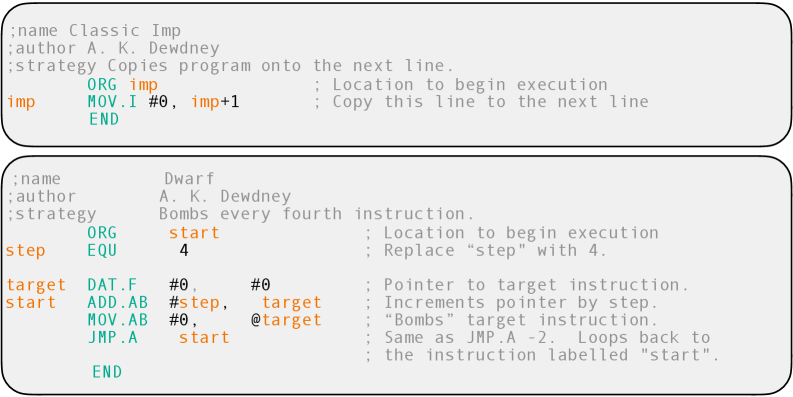
Adversarial Program Evolution with LLMs
Digital Red Queen (DRQ) introduces an algorithm where LLMs evolve assembly-like programs called “warriors” that compete for control of a virtual machine in the game of Core War. Rather than optimizing toward static objectives, DRQ embraces “Red Queen” dynamics where goals continually shift based on competition, demonstrating how adversarial self-play can drive the evolution of increasingly sophisticated programs.
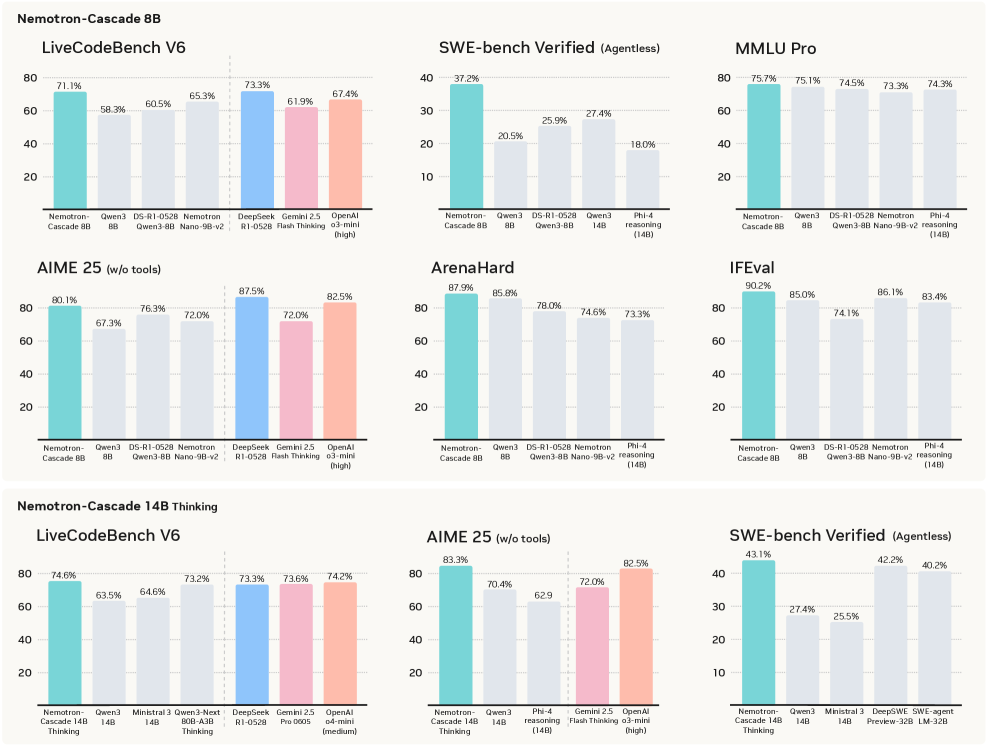
Nemotron-Cascade
Nemotron-Cascade introduces cascaded domain-wise reinforcement learning (Cascade RL) to build general-purpose reasoning models capable of operating in both instruct and deep thinking modes. Rather than blending heterogeneous prompts from different domains, Cascade RL orchestrates sequential, domain-wise RL stages that reduce engineering complexity while delivering state-of-the-art performance.
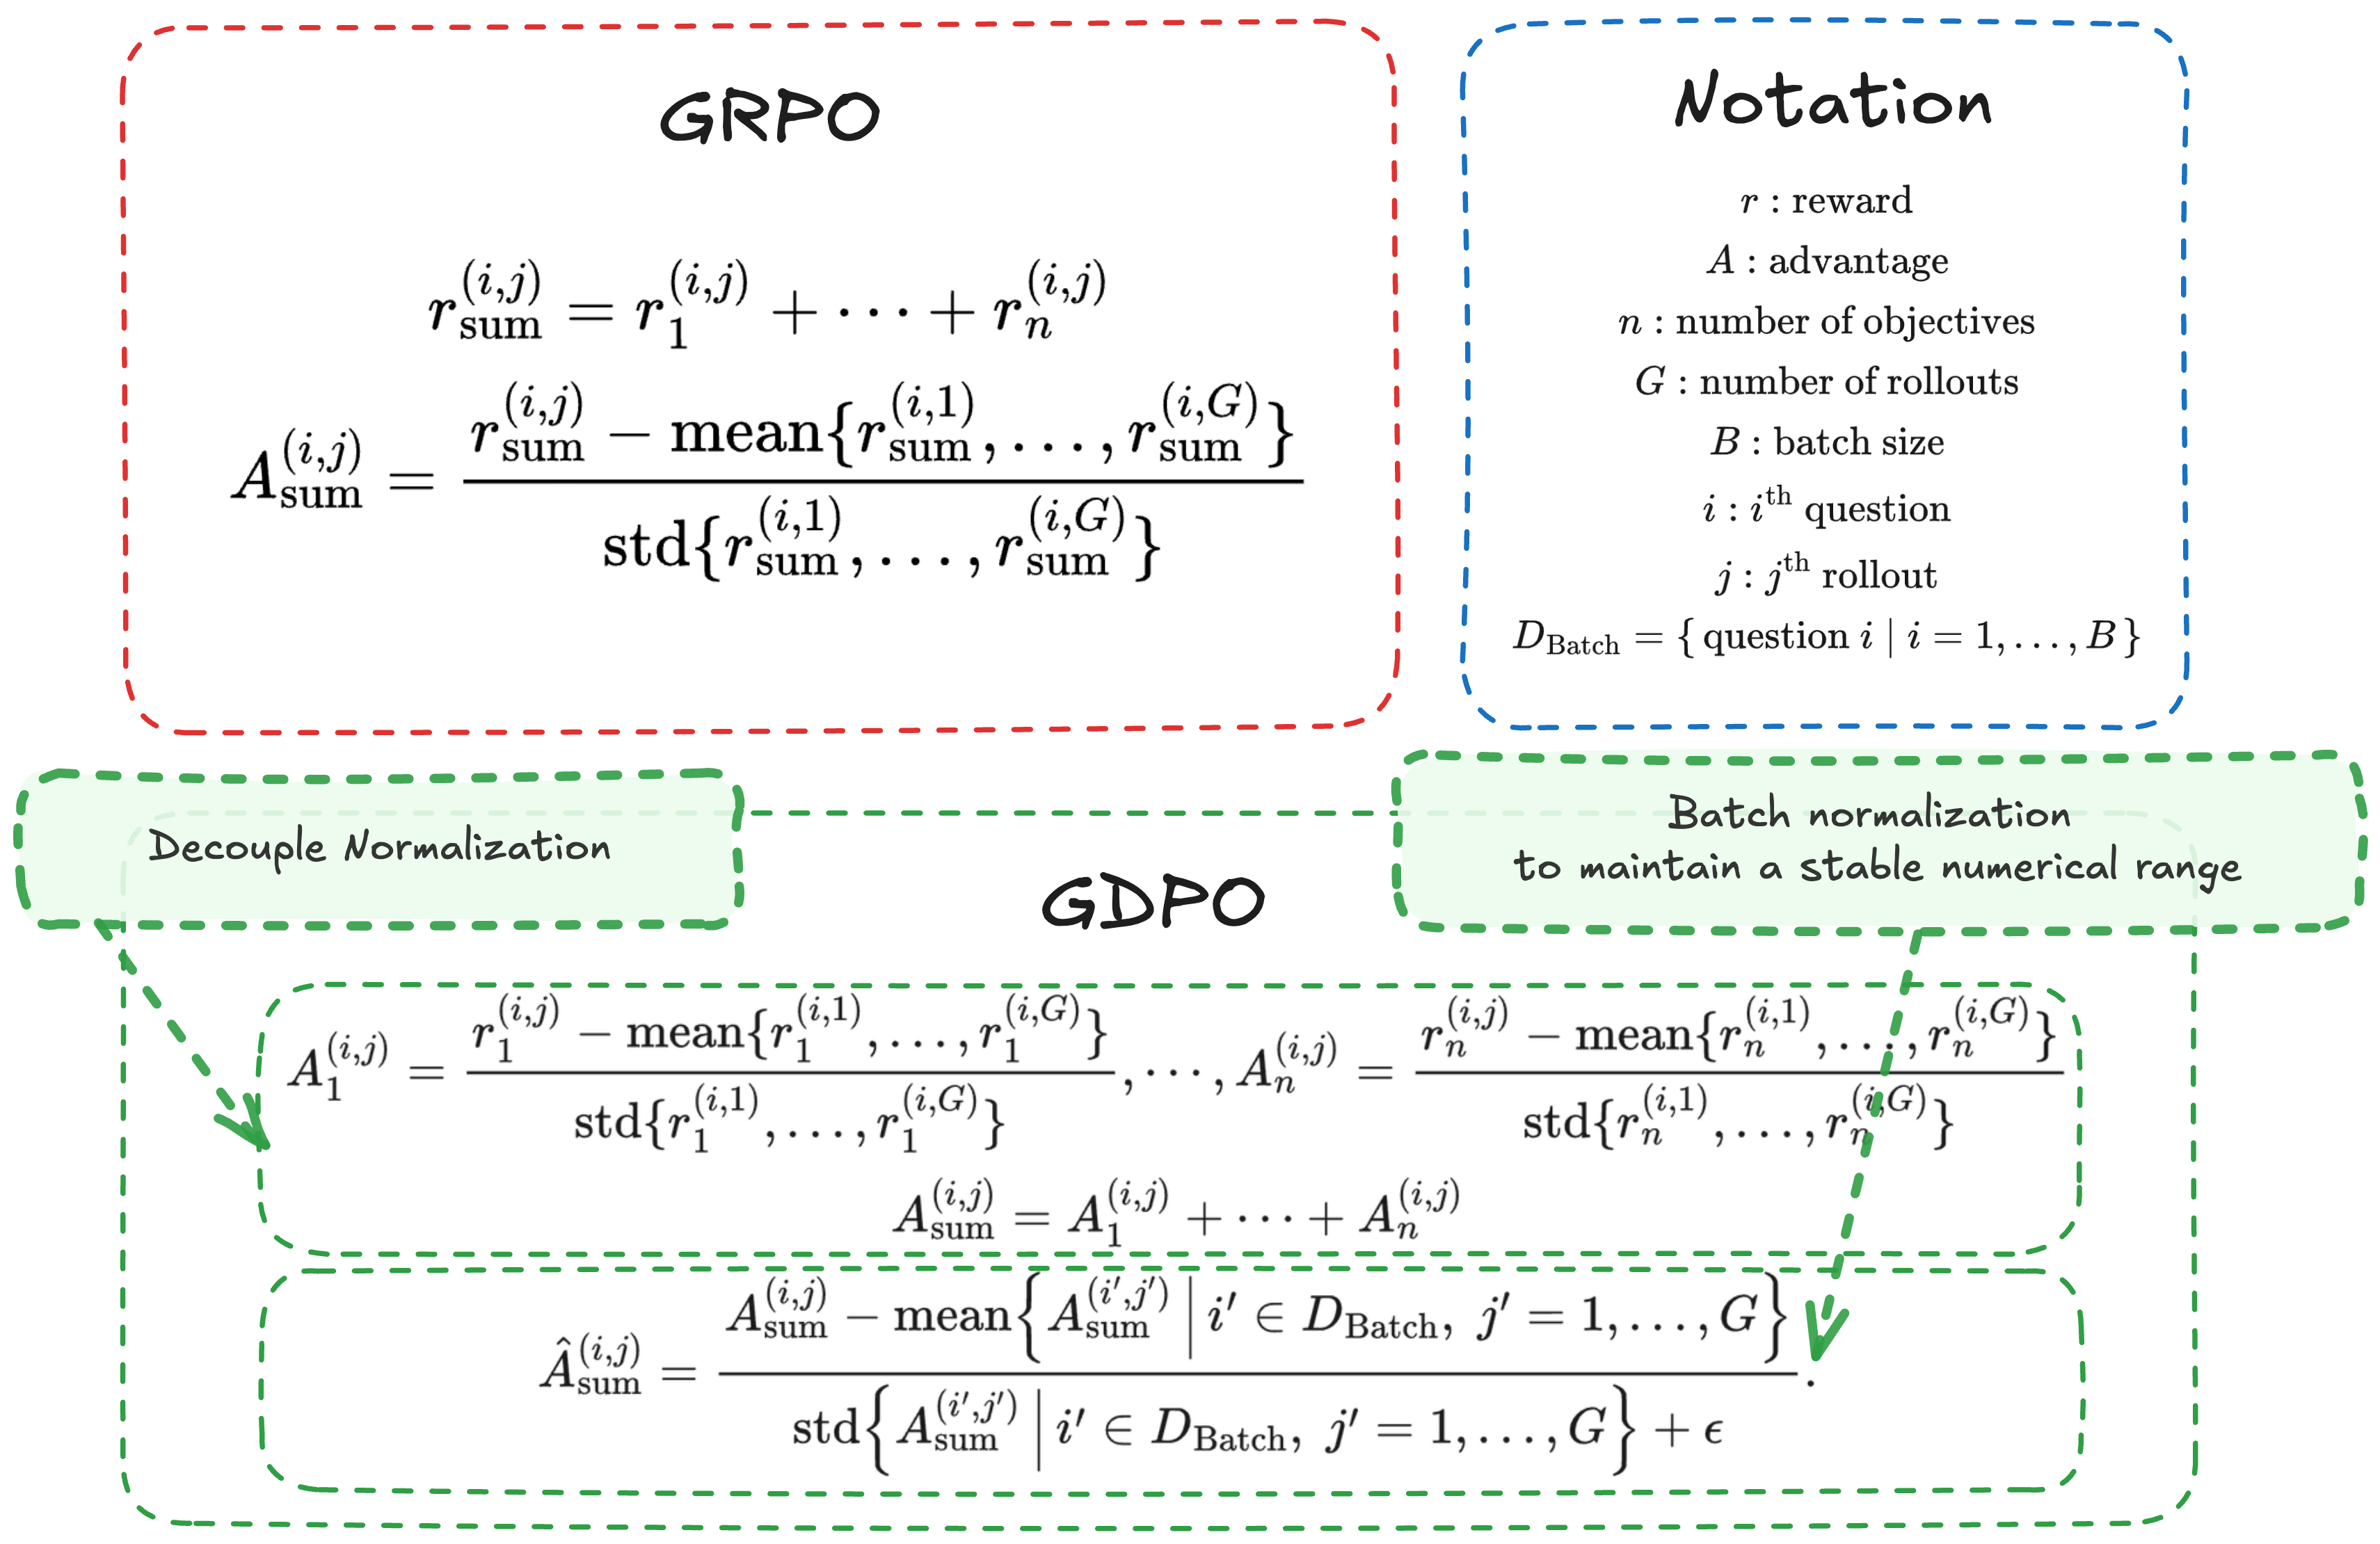
GDPO
GDPO addresses a critical flaw in training language models with multiple competing objectives. The authors discover that when applying Group Relative Policy Optimization (GRPO) to multi-reward settings, normalizing distinct rollout reward combinations causes them to collapse into identical advantage values, degrading training signal quality and stability.
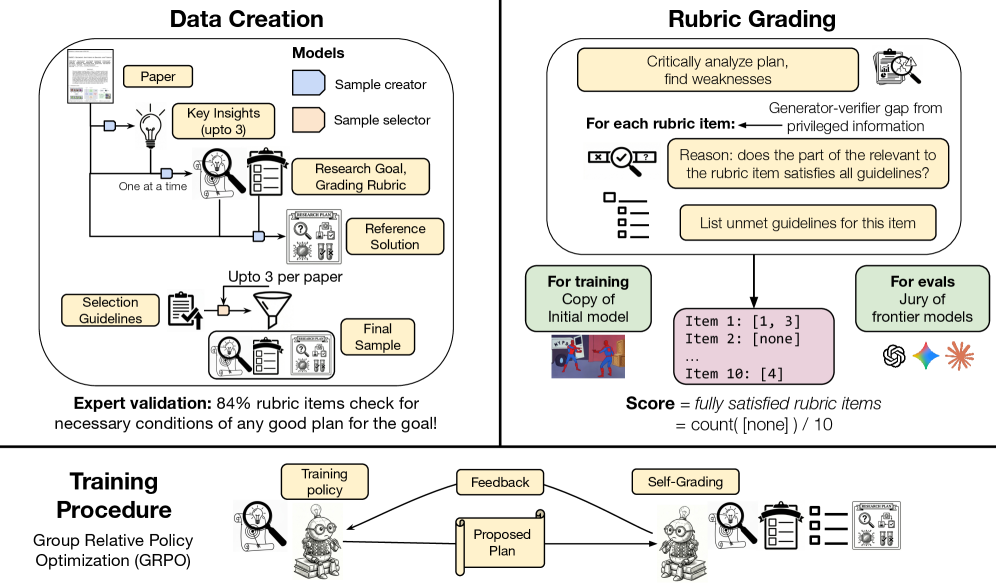
Training AI Co-Scientists Using Rubric Rewards
This paper from Meta Superintelligence Labs presents a scalable method to train language models to generate better research plans without expensive human supervision or real-world execution. The approach automatically extracts research goals and goal-specific grading rubrics from scientific papers, then uses reinforcement learning with self-grading to improve plan generation.
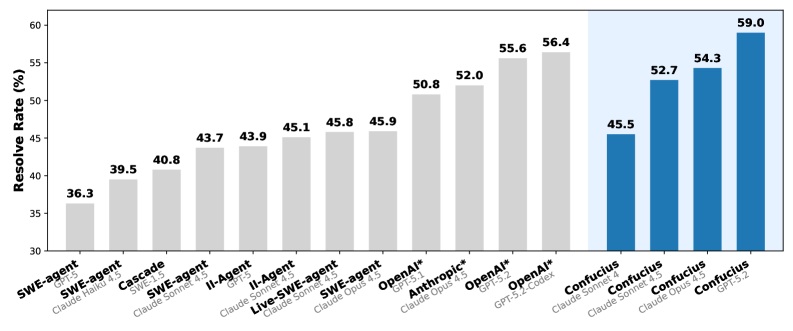
Confucius Code Agent
Confucius Code Agent (CCA) is a software engineering agent designed to operate on large-scale codebases. Built on the Confucius SDK, it introduces a three-axis design philosophy separating Agent Experience (AX), User Experience (UX), and Developer Experience (DX) to enable robust multi-step reasoning and modular tool use.
SciSciGPT
SciSciGPT is an open-source AI collaborator that uses the science of science domain as a testbed for LLM-powered research tools. Its multi-agent architecture with five specialized modules automates complex research workflows and completes tasks in about 10% of the time required by experienced researchers while producing higher-quality outputs.
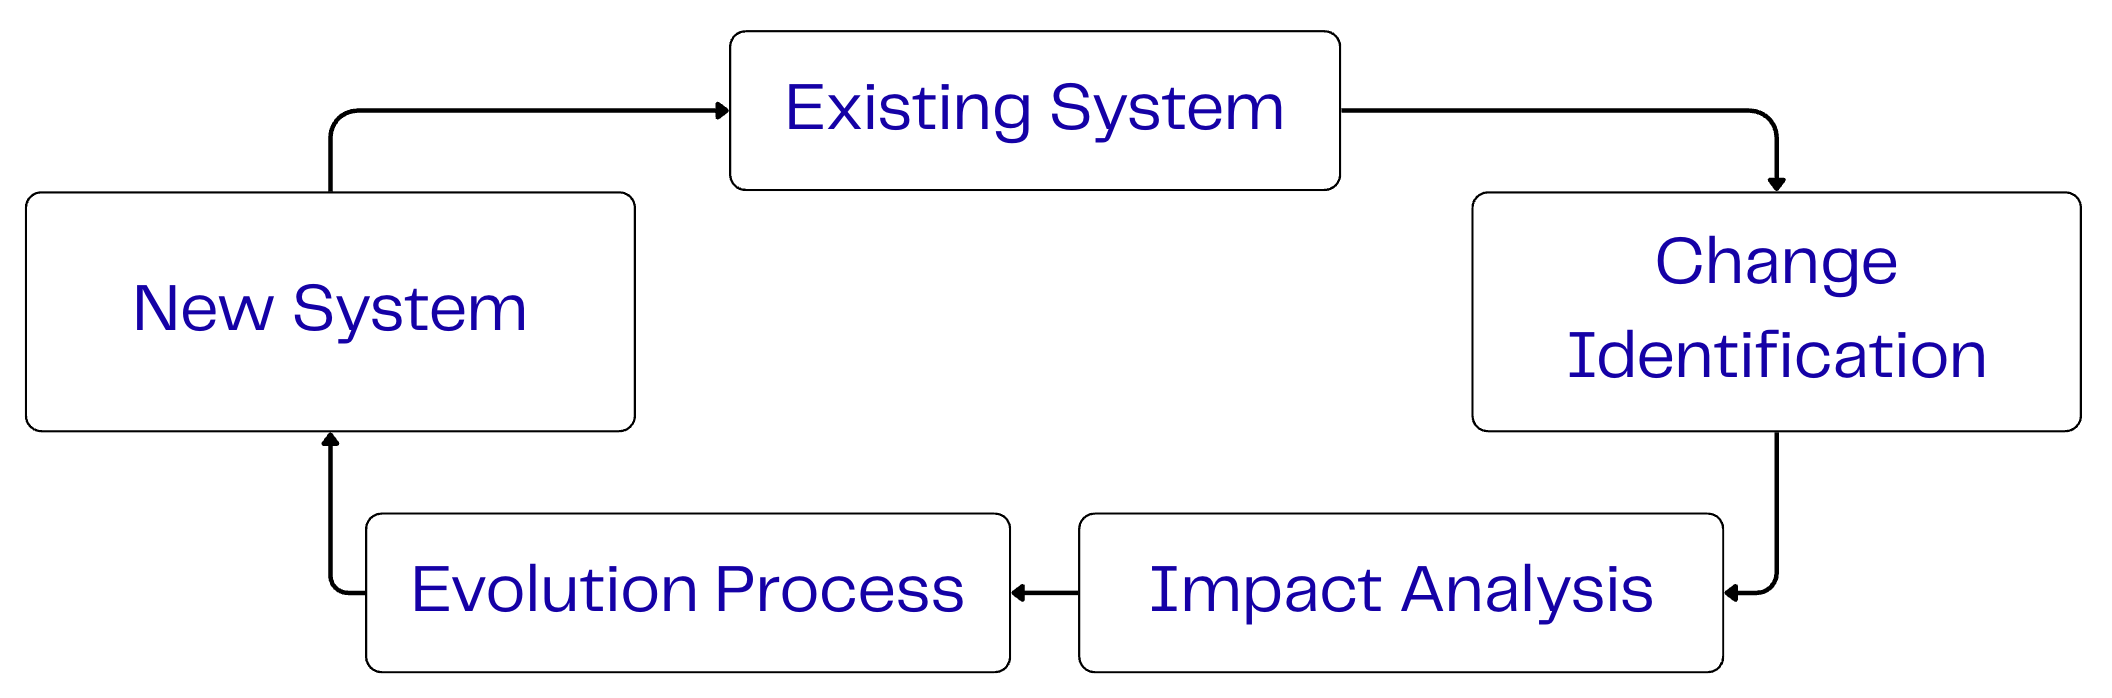
SWE-EVO
SWE-EVO introduces a benchmark for evaluating coding agents on long-horizon software evolution tasks that require multi-step modifications spanning an average of 21 files per task. The benchmark reveals significant limitations of current agents: GPT-5 with OpenHands achieves only 21% on SWE-EVO compared to 65% on SWE-Bench Verified, highlighting the gap between isolated bug fixes and realistic software development scenarios.
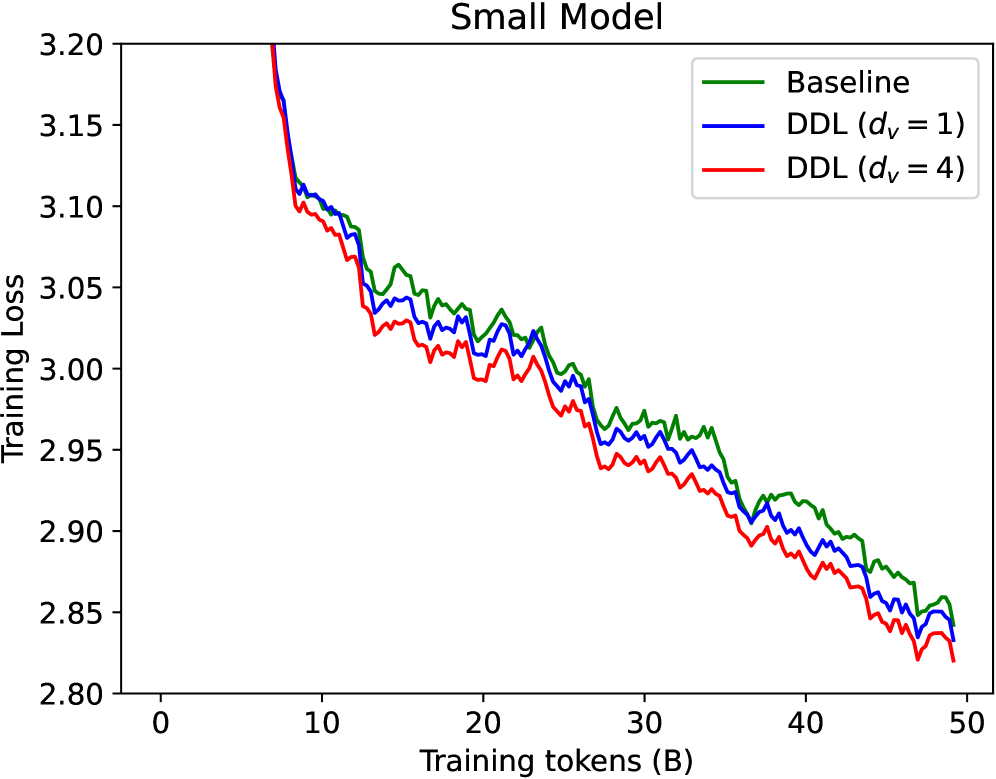
Deep Delta Learning
Deep Delta Learning introduces a novel “Delta Operator” that generalizes residual connections by modulating the identity shortcut with a learnable, data-dependent geometric transformation. This enables networks to dynamically interpolate between identity mapping, orthogonal projection, and geometric reflection, allowing selective forgetting of features rather than just accumulation.
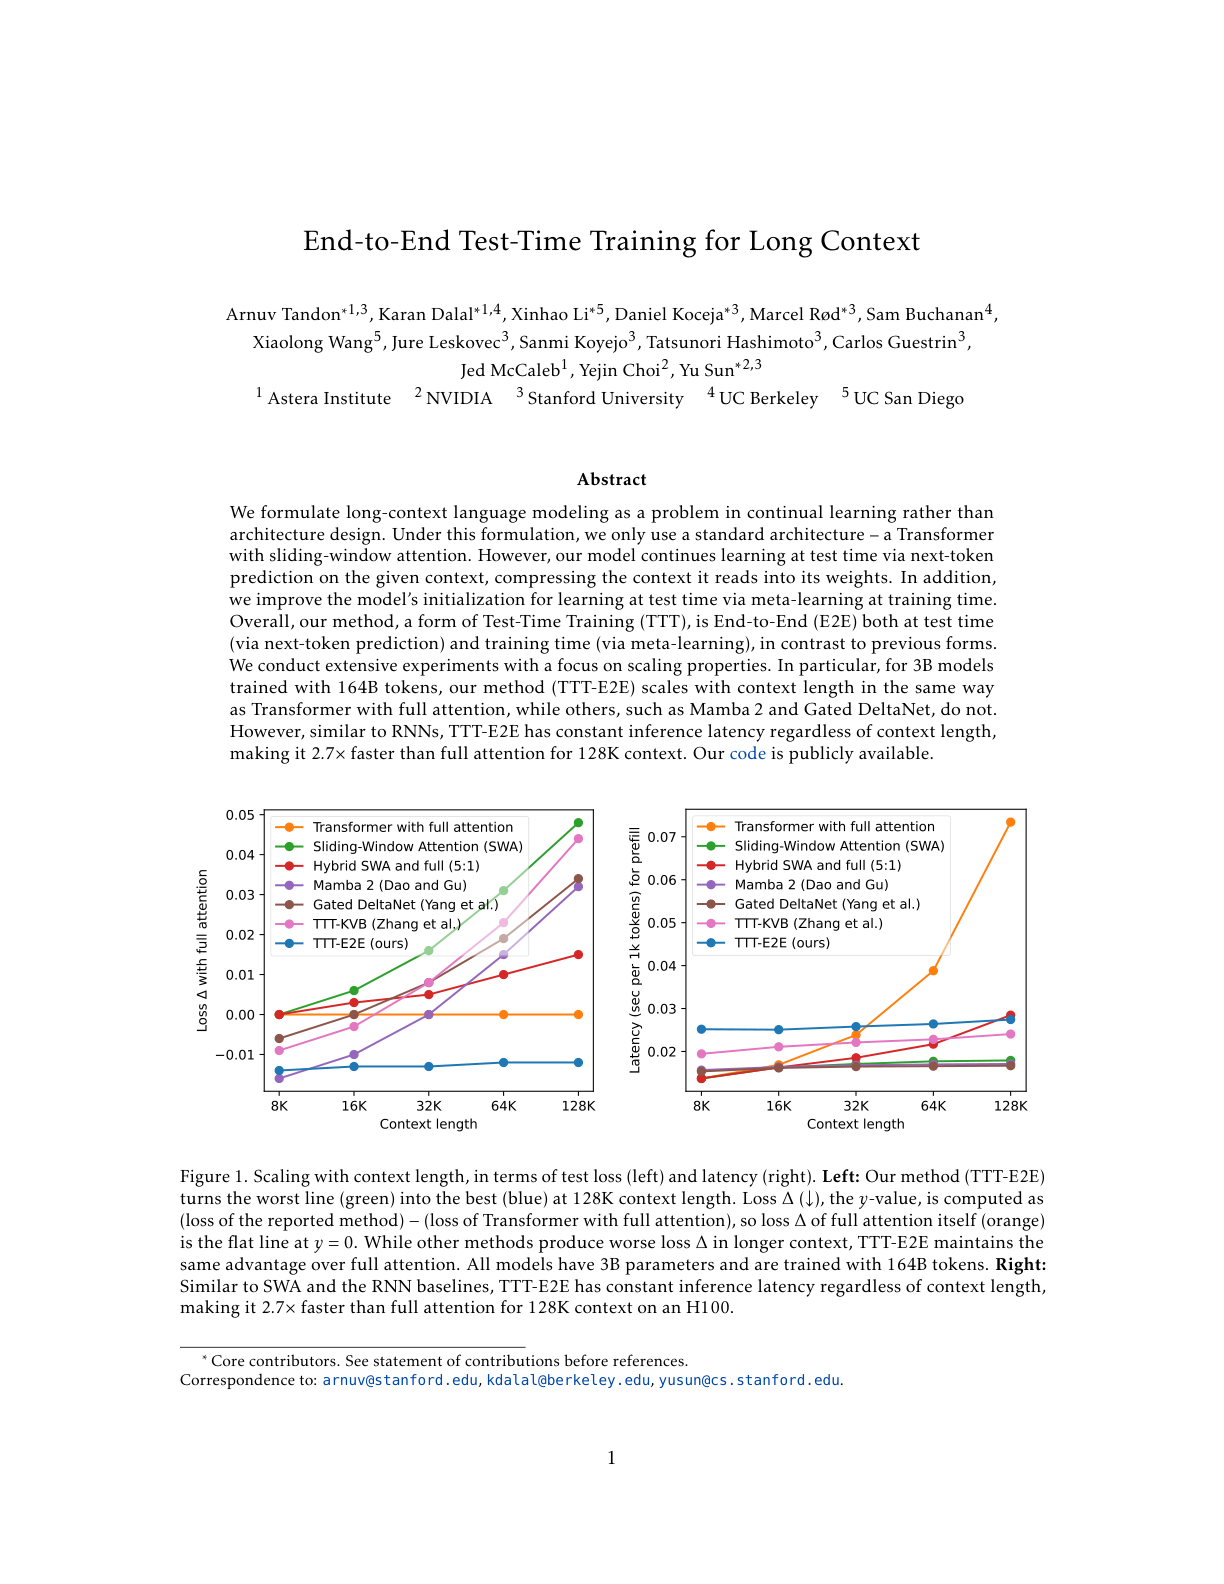
End-to-End Test-Time Training for Long Context
This paper reframes long-context language modeling as a continual learning problem rather than architecture design. TTT-E2E uses a standard Transformer with sliding-window attention that continues learning at test time via next-token prediction, compressing context into its weights rather than storing all key-value pairs.
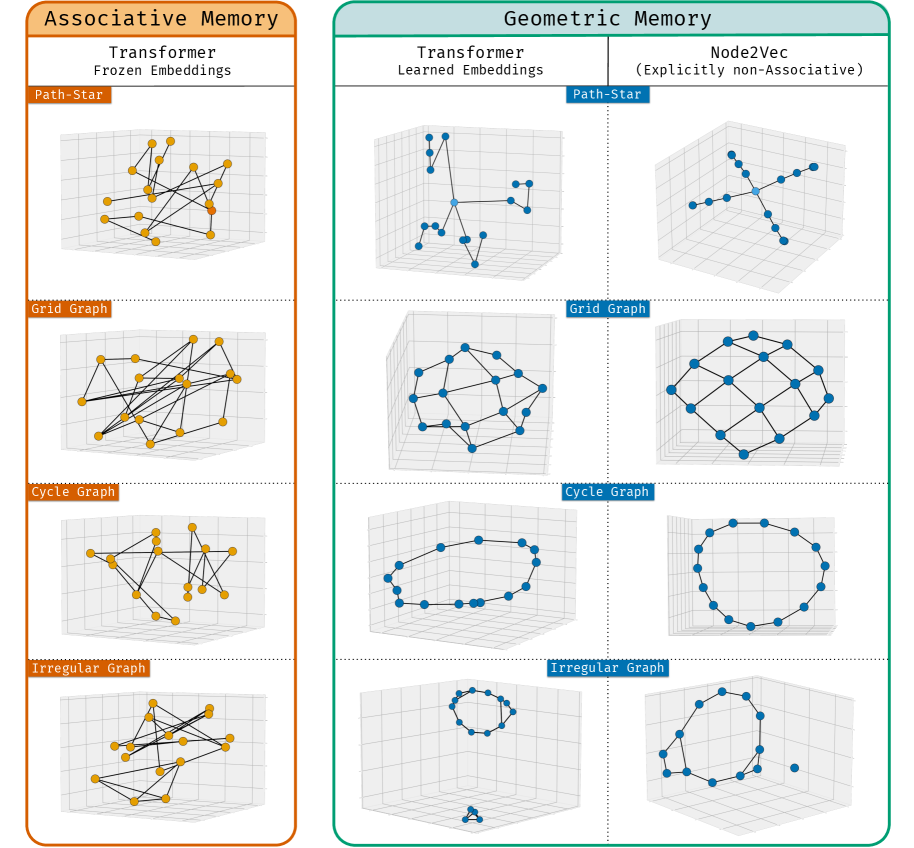
Geometric Memory in Sequence Models
This paper identifies a dramatically different form of how deep sequence models store factual information called geometric memory, contrasting with the traditional associative memory view. Models synthesize embeddings encoding global relationships between all entities, even ones that never co-occur in training.
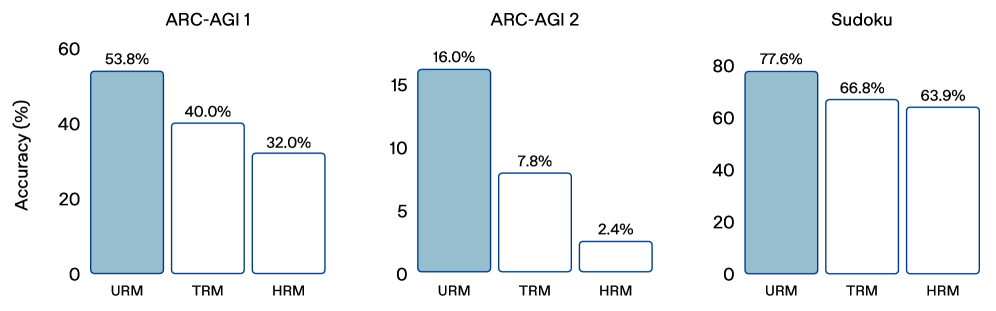
Universal Reasoning Model
This paper investigates why universal transformers excel at complex reasoning tasks like ARC-AGI. The key finding: performance gains come primarily from recurrent inductive bias and strong nonlinear components rather than elaborate architectural designs.
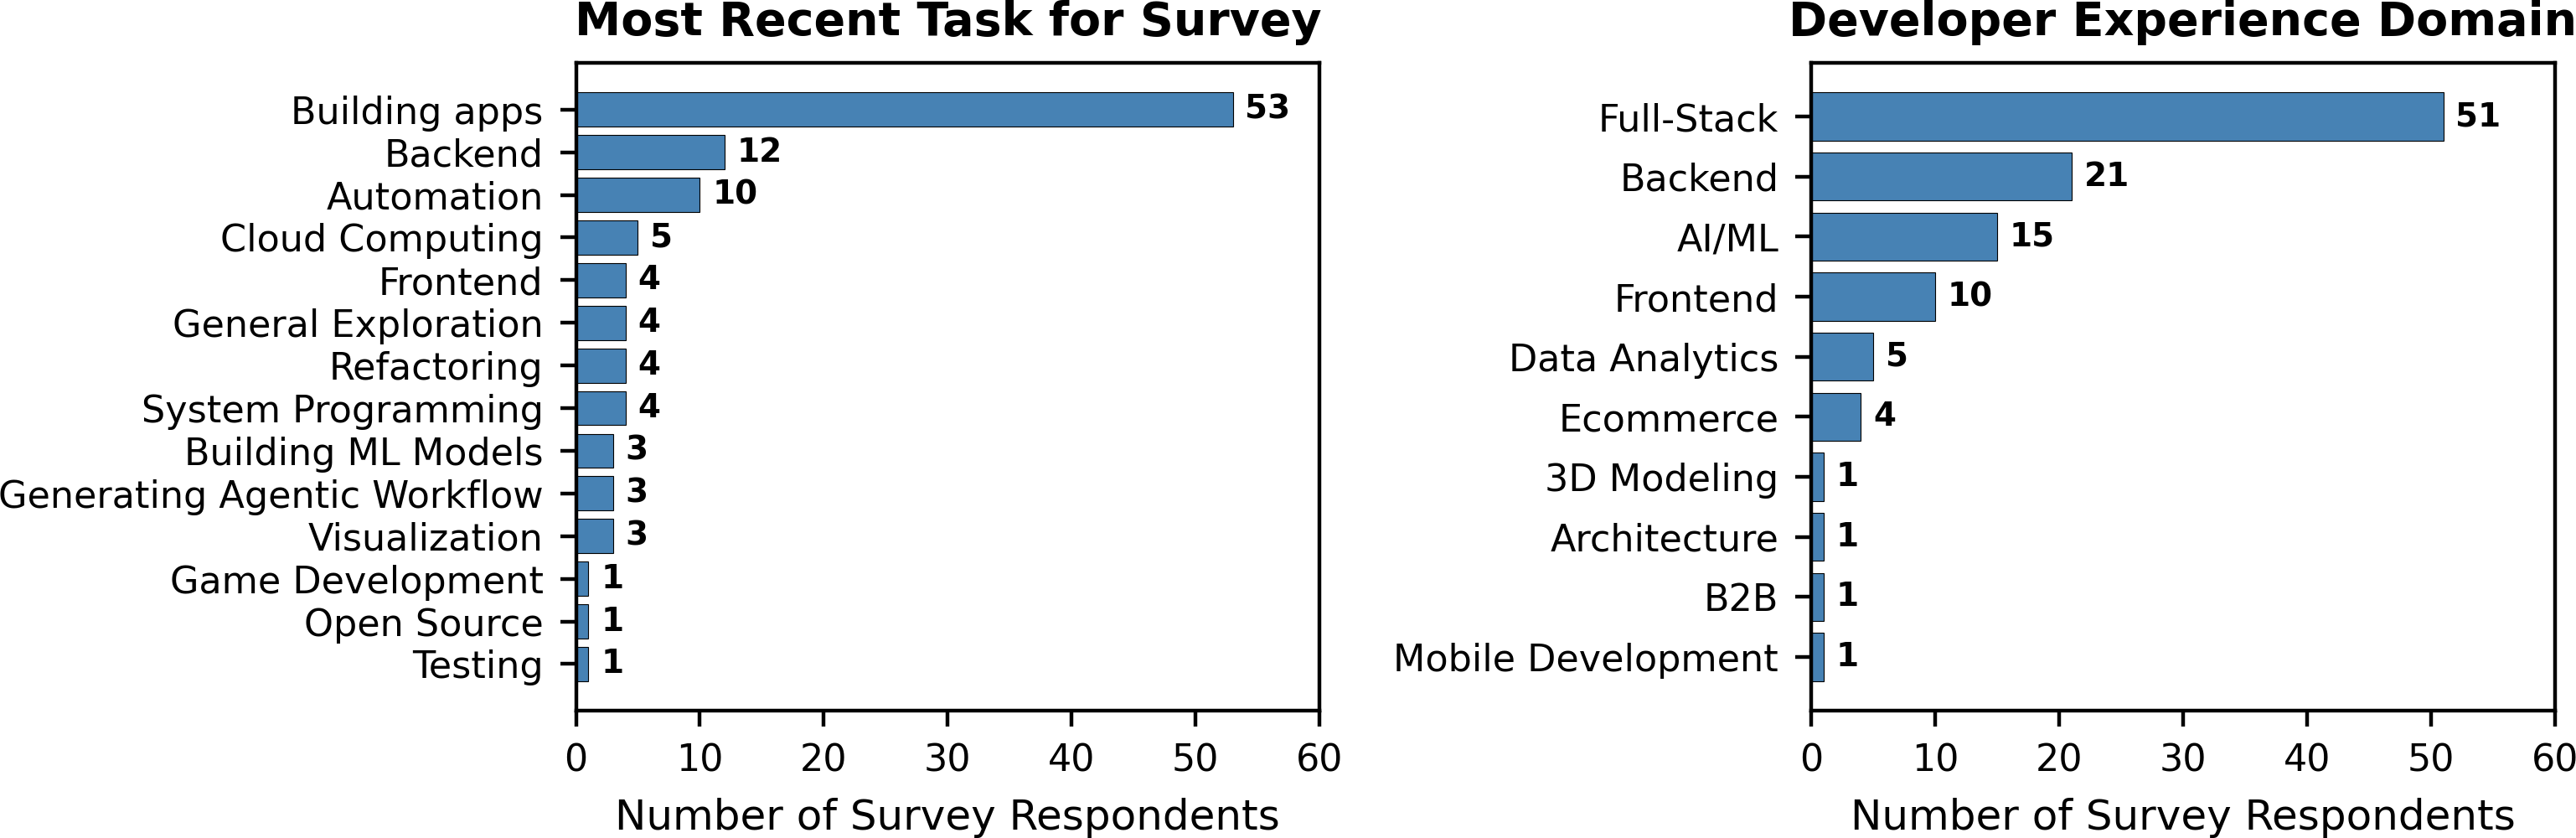
AI Agents for Coding in 2025
This study from UC San Diego and Cornell examines how experienced software developers (3+ years) actually use AI coding agents, through field observations (N=13) and surveys (N=99). The key finding: professional developers don’t “vibe code” - they carefully control agents through planning and supervision.